

Configure and verify
Choose the approach that fits your workflow: configure one coding agent from the console or CLI, or apply shared settings to a squad or organization.- Console
- CLI
- Squad
- Organization
- Click your coding agent’s icon in the console header.
- Under Token Compression, turn Tool Result Trimming, Tool Surface Reduction, and Output Brevity on or off independently.
- Click Save. These choices apply to the selected coding-agent key.
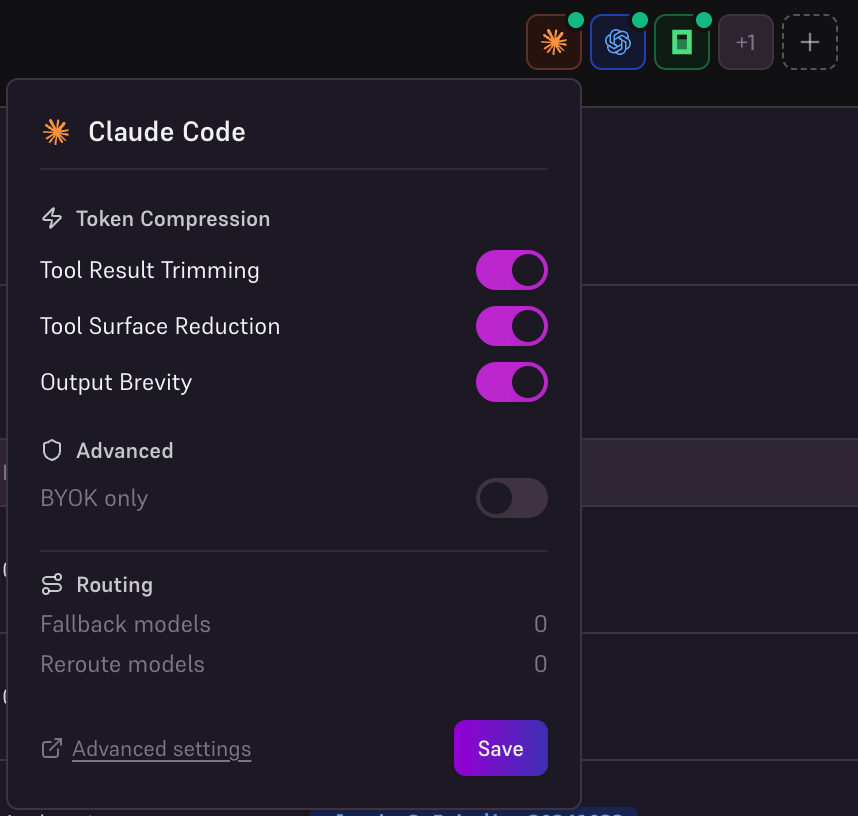
Control each compression strategy from your coding agent's menu.
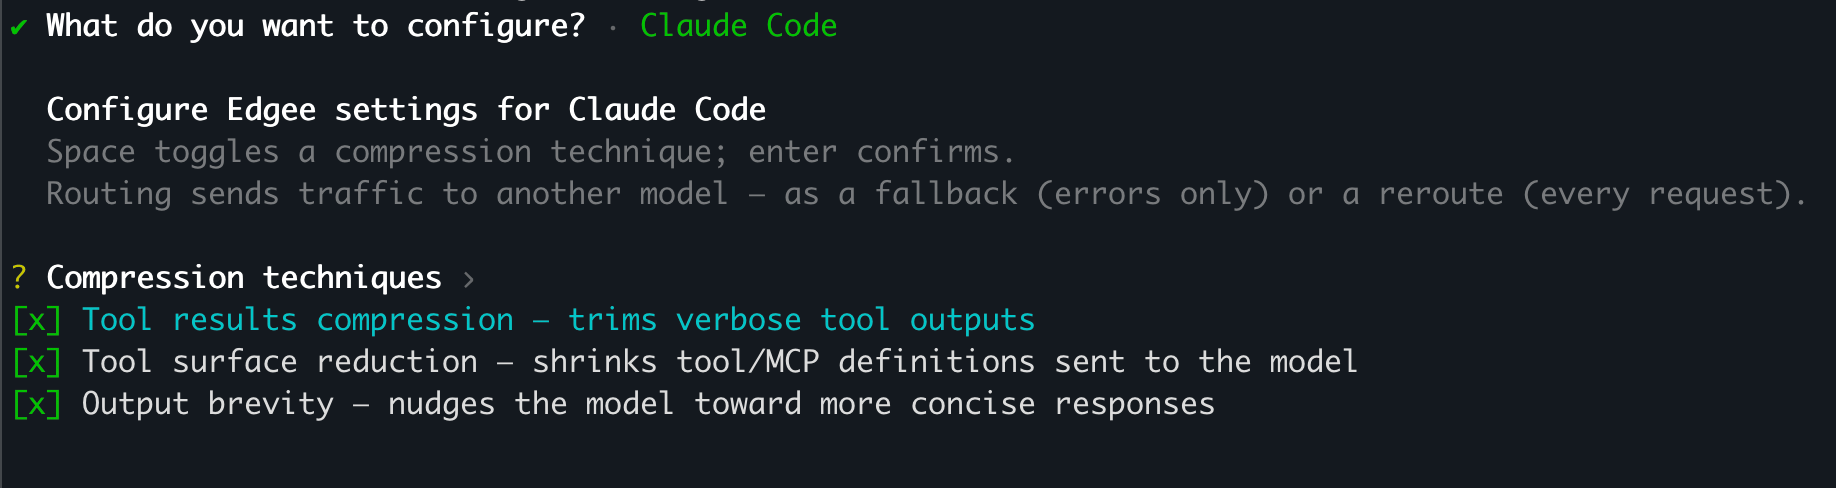
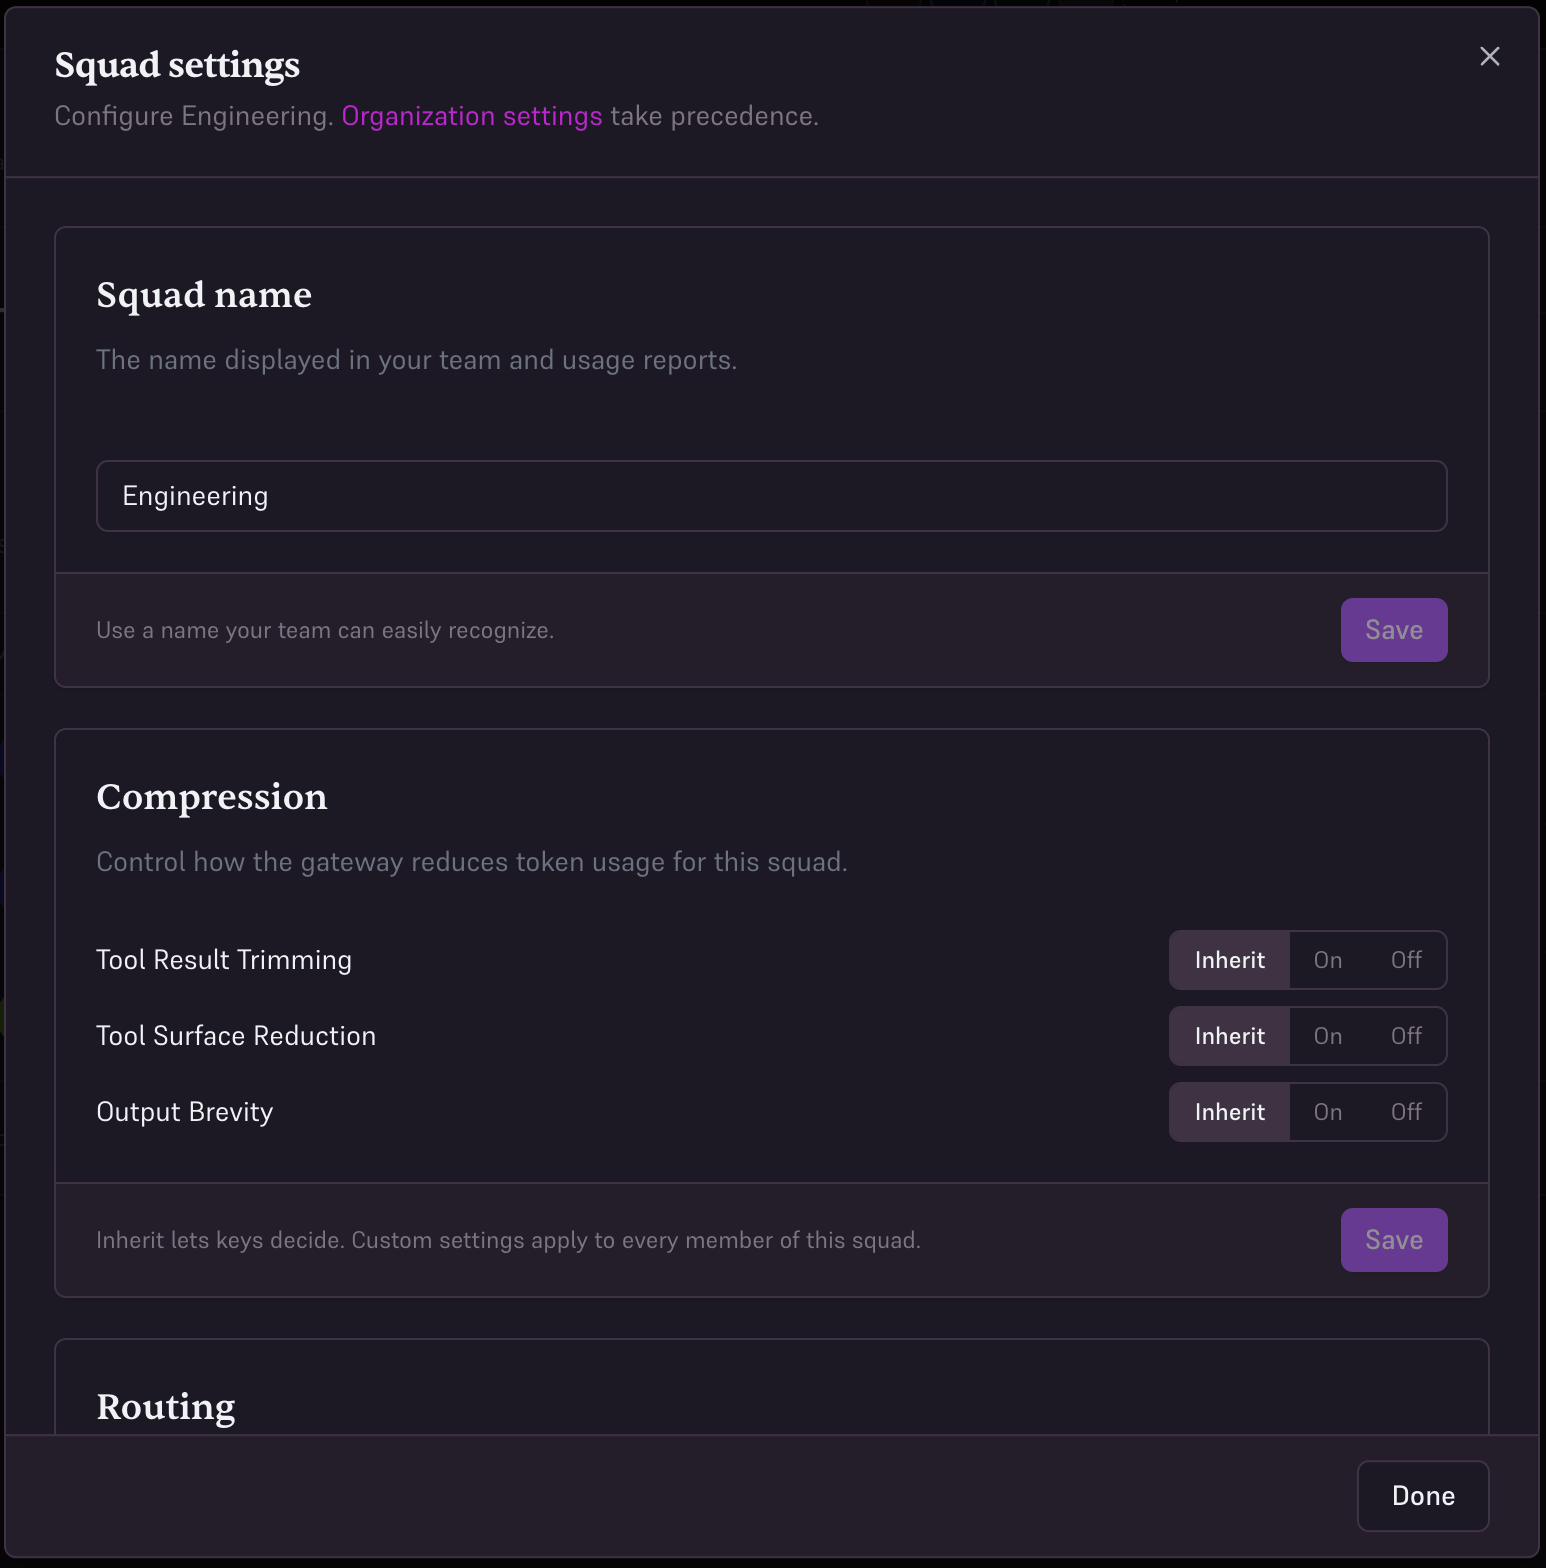
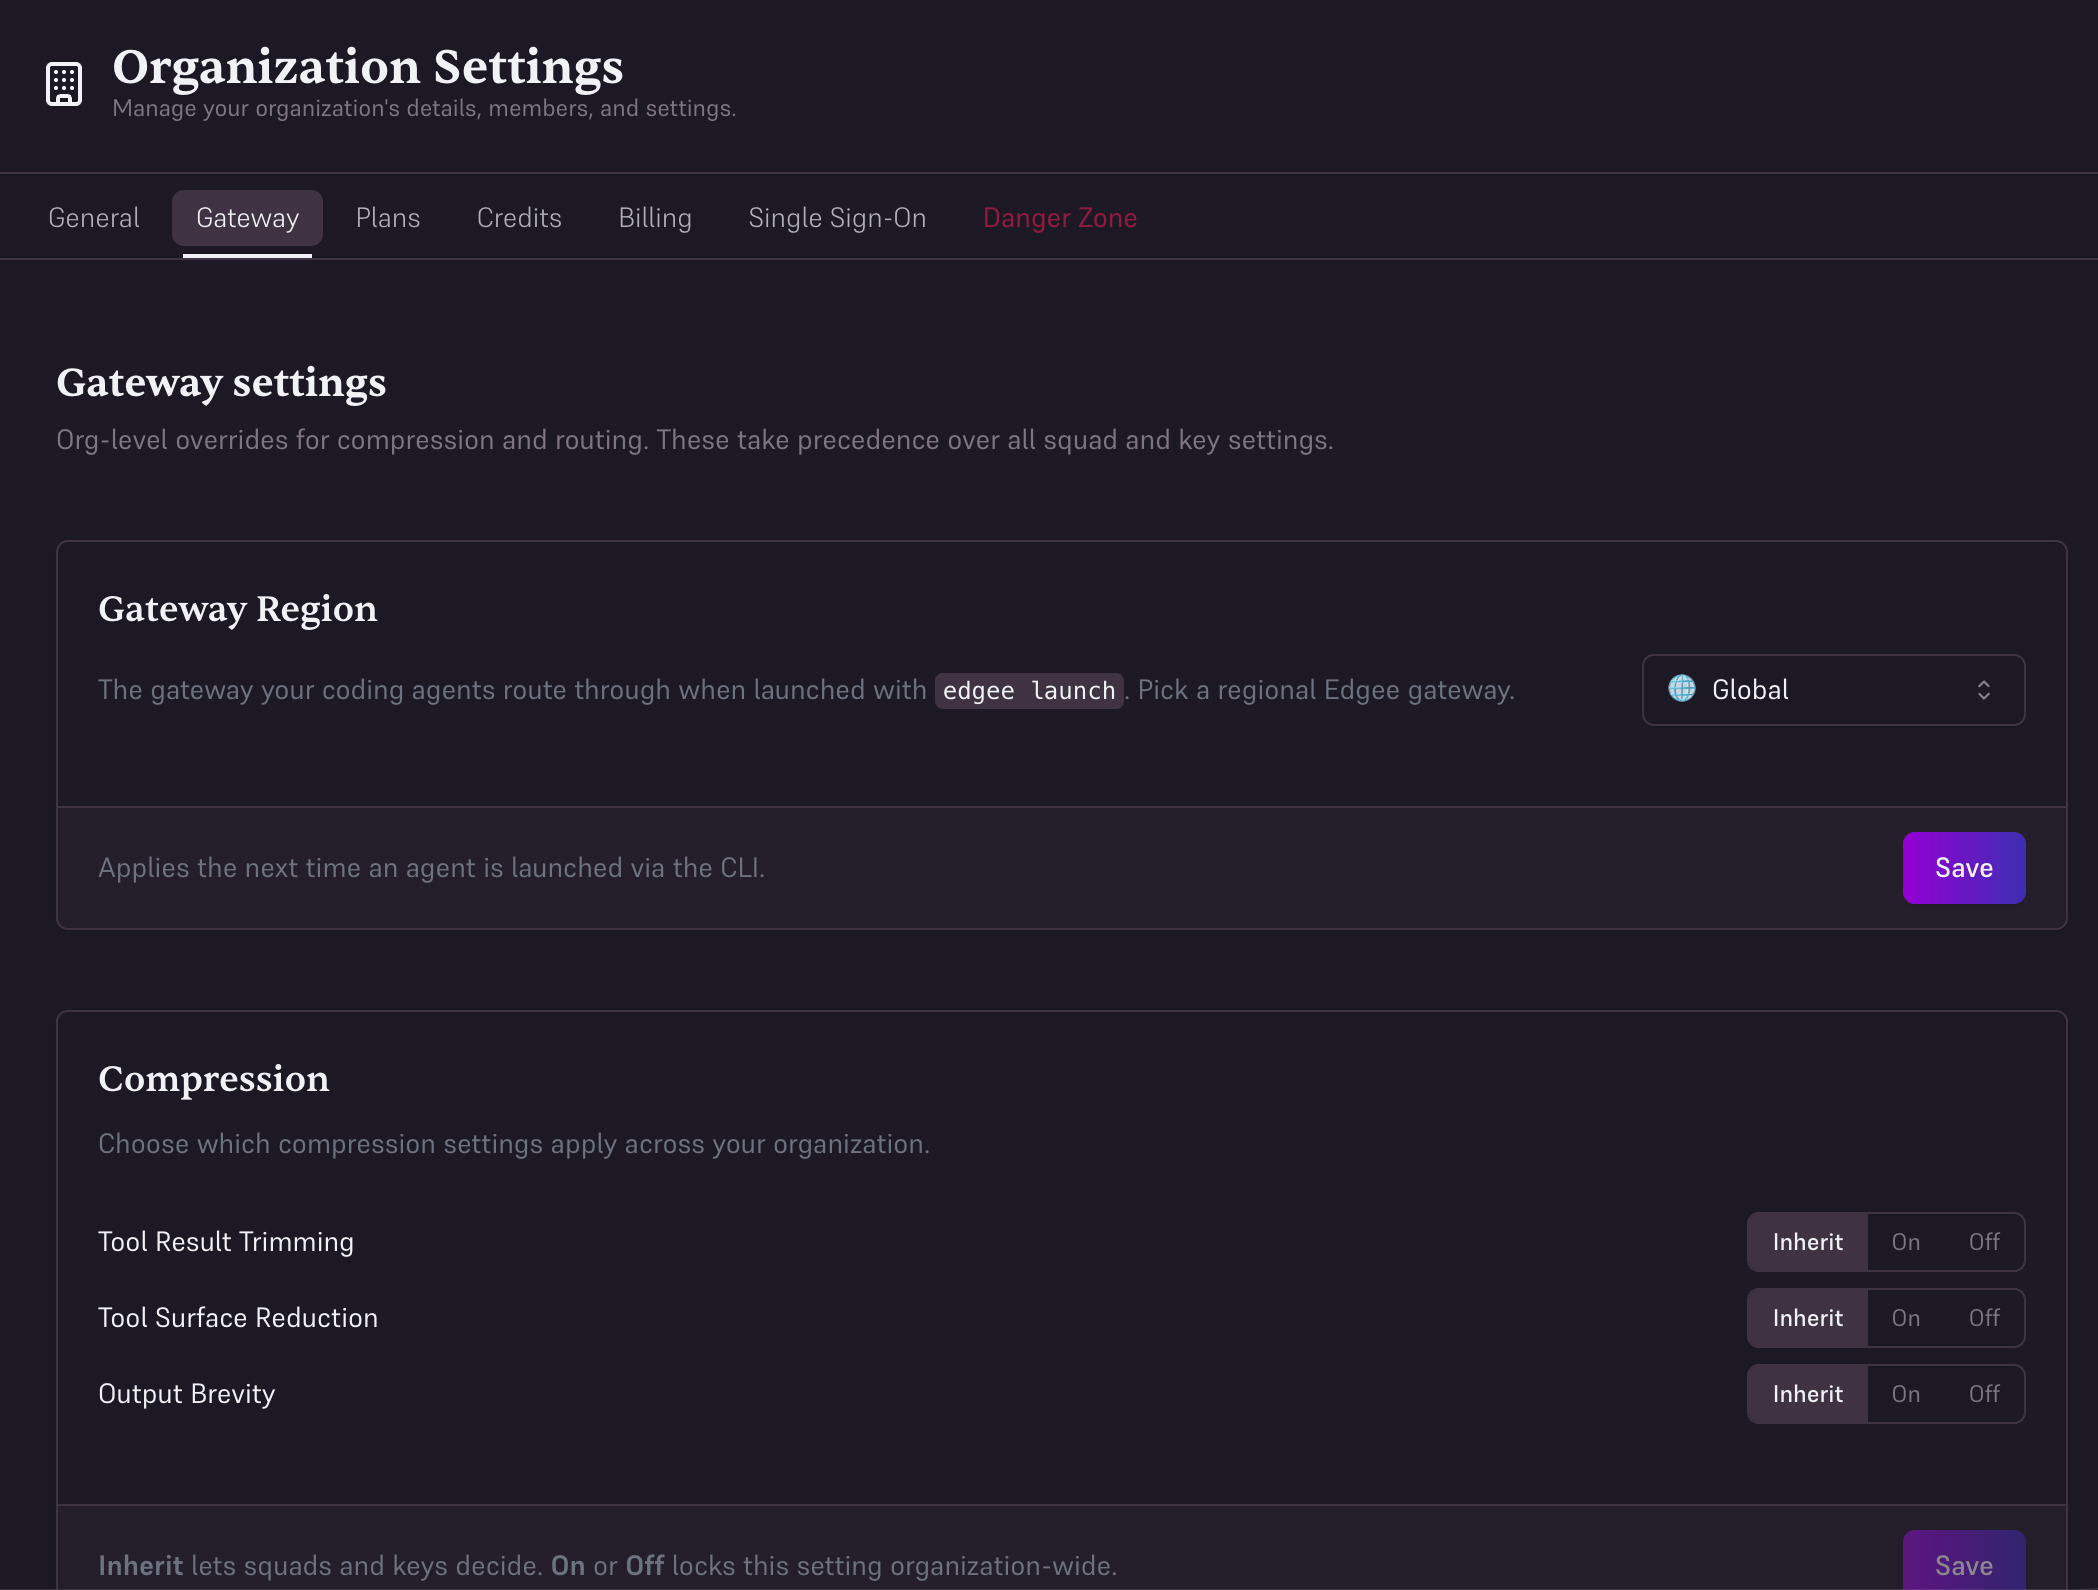
Shared settings take priority: organization → squad → agent. A console switch marked Enforced by Org or Enforced by Squad is locked; CLI changes cannot override that policy either. See setting inheritance.
What you’ll actually save
Two numbers circulate about Edgee compression. They measure different things, and mixing them up is how a budget forecast goes wrong.
The benchmark lands higher because SWE-bench Lite runs long autonomous coding sessions, which is the exact shape
output_brevity is best at. Real teams run a mix of short questions, reviews, tool-heavy queries and long sessions, so the average sits well below the benchmark. Sessions are shorter, some agents are already tuned for terseness, and most teams enable a subset of the three strategies per key.
Every figure on this page is labelled with which of the two it belongs to. They sit on different baselines and must never be added together.
Full methodology, including what each strategy measured on its own: Measuring token compression for coding agents on SWE-bench Lite, by Khaled Maâmra, Research Engineer at Edgee.
The three compression strategies
Edgee ships three named compression strategies, toggleable independently. Compression sharpenstool_result_trimming, adds tool_surface_reduction as a new Layer 1 technique, and adds output_brevity as a new Layer 2 technique.
Benchmark figures, not customer averages. They are one SWE-bench Lite session (18,420 → 9,210 tokens with all three on, a −50% reduction), expressed as each strategy’s share of that session. The shares are absolute token counts, so they add up; percentages on different baselines never do.
Tool Result Trimming
Filterstool_result messages before they reach the model. Strips:
- Boilerplate framing
- Pagination markers
- ANSI escape sequences
- Repeated headers
- Verbose JSON wrappers
- File contents — output from Read tool and file system operations.
- Grep and search outputs — code search, ripgrep, similar tools.
- Shell command output — stdout/stderr from Bash and terminal commands.
- API responses — large JSON or text payloads returned by tool calls.
- Database query results — rows and records returned from tool-executed queries.
tool_result payloads — the model receives the same technical content, with redundant framing removed.
Measured on SWE-bench Lite. 10.4% median per-task cost reduction over 6 tasks, 4 of 6 favoring Edgee. Directional rather than statistically significant at that sample size, and the cleanest gains show on long sessions where tool output accumulates.
Initially based on rtk-ai/rtk, we built our tool result compression strategy directly into the Edgee Rust gateway, so users don’t need a separate binary in their pipeline.
Tool Surface Reduction
Coding agents connect multiple MCP servers, each exposing its own set of tools. The agent sends the full tool list to the model on every request, even when only one or two MCP servers are relevant. This bloats context and drives up cost. How it works: Edgee creates a virtual MCP server that the model sees. Instead of the full tool list, the model talks to the virtual MCP. The virtual MCP classifies the user’s task and searches for the correct real MCP server to use. It sends the result back to the client, which then executes the real MCP server. The result is a tool-aware gateway:- The IDE still exposes all MCP servers — nothing changes for the developer’s setup.
- The agent still discovers tools through the standard MCP protocol — nothing changes for the agent’s behavior.
- The model only ever sees the virtual MCP. The client receives the routing decision from it and executes the real MCP server.
Output Brevity
Reduces verbosity in model responses without losing technical content. Same answer, fewer tokens. Single flag — no level parameter. For coding-agent sessions, output is a small share of total token volume (~1%), sooutput_brevity is opt-in and disabled by default. For chat-style or RAG workloads where the model produces long-form answers, output is the dominant cost and output_brevity becomes the lever.
Measured on SWE-bench Lite. 27.5% median per-task cost reduction over 6 tasks, 6 of 6 favoring Edgee, paired sign test p = 0.031. Bootstrap 95% confidence interval on the token ratio is 0.41x to 0.84x, entirely below 1. This is the strongest of the three on autonomous coding work, because it attacks output, the most expensive token class, without touching the prefix or disturbing cache amortization.
Academic note. Recent work supports the broader claim — Brevity Constraints Reverse Performance Hierarchies in Language Models (Hakim, arXiv:2604.00025, March 2026) found that constraining models to brief responses can improve accuracy on certain benchmarks. The study is on open-weight models, not Claude/GPT directly.
Reading the compression block
For native SDK response fields, see Application observability. For coding assistants, inspect compression in the console’s session report and Logs.
Enabling and disabling
Choose the scope where the setting should apply.CLI (default-on for coding agents)
When you launch a coding agent through the Edgee CLI,tool_result_trimming is enabled automatically — no console step required.
tool_surface_reduction is opt-in. output_brevity is opt-in for coding-agent sessions because output is a small share of their volume.
Console (per-key toggle)
In the console, open Team and manage the relevant agent, or use Org. Settings → Gateway for organization settings. For team-managed keys, the same toggles are available per-member from Team → agent settings. See Team management.Receipts
In production. Across active customers, rolling 30 days, token bills fall 15-20% from compression alone, with zero measurable drift on SWE-Bench Verified samples. This is the figure to plan a budget around. On SWE-bench Lite. With all three strategies on, cost falls 50%. Per strategy, on the workload each one targets:tool_result_trimming— 10.4% median per-task cost, 4/6 tasks favoring Edgee (directional)tool_surface_reduction— 33.0% fewer tokens on MCP workloads, 8/8, p = 0.008, for roughly 10% costoutput_brevity— 27.5% median per-task cost, 6/6, p = 0.031
Next
Observability
Track token usage, costs, and compression events per session and per team.